
Perplexity divides AI inference between personal computers and the cloud to reduce expenses.
Perplexity AI introduced a platform at Computex that facilitates real-time routing of AI inference between PCs and cloud servers, functioning as an “air-traffic controller” for AI operations. This chip-agnostic system aims to address the cost issues associated with centralized inference as Perplexity's revenue reaches $500 million.
Perplexity AI's platform intelligently divides AI tasks between personal computers and cloud servers, determining in real time which computations can be executed on a PC’s processor and which require the capabilities of data center hardware. During an announcement at Computex in Taipei, CEO Aravind Srinivas referred to the system as an “air-traffic controller for AI tasks," aiming to lower inference costs, which involve running trained AI models to produce responses.
“You don’t want all your compute centralized in servers with everything running through the largest models,” Srinivas commented in a Bloomberg Television interview. “You’re already seeing reports of companies panicking over costs. Some are spending as much as half a billion dollars a month. What you really want is efficient value per watt per user.”
**How it works**
The system assesses each AI task and directs it to the most effective computing layer. Basic tasks manageable by modern PC processors, such as summarization, formatting, or lightweight classification, are executed locally without cloud interaction. In contrast, more complicated tasks that require extensive model inference, like multi-step reasoning or retrieval-augmented generation utilizing vast datasets, are directed to cloud servers. This routing occurs in real time and is seamless to the user.
The outcome is that Perplexity can accommodate more users at reduced costs by shifting some inference responsibilities to the billions of PCs that are already in use. As the demand for AI inference burdens data center capabilities and pushes utilities to plan for $1.4 trillion in grid enhancements, distributing computing to the edge becomes both an economic and infrastructure imperative.
Srinivas shared the stage with Intel CEO Lip-Bu Tan, whose company is a major player in the PC processor market and has a vested interest in establishing PCs as an important layer for AI computation. Nevertheless, Srinivas emphasized that the platform is “chip agnostic” and is compatible with Nvidia processors as well. Nvidia also spotlighted this trend towards edge inference at Computex with its new RTX Spark platform for AI-powered laptops and desktops.
**The cost problem**
Srinivas's comments on firms "spending half a billion dollars per month" on AI compute are not exaggerated. OpenAI’s infrastructure costs have been documented at that magnitude, and Anthropic is projecting $10.9 billion in revenue for Q2, which includes significant compute expenses that squeeze profit margins. The financial and energy burdens associated with centralized AI inference represent a key limitation of the current AI boom.
Perplexity’s approach challenges the notion that AI inference must occur in the cloud. By recognizing the PC as a primary compute node instead of a mere thin client, the company can lower its own server expenses while likely providing quicker responses for tasks handled locally. However, this introduces complexity: the routing system must accurately judge task difficulty in milliseconds, and the quality of local inference relies on the user’s hardware capabilities.
**Revenue efficiency**
Perplexity’s financial growth highlights the importance of cost efficiency. Srinivas reported on X in April that the company’s revenue surged fivefold, from $100 million to $500 million, while its workforce grew by only 34%. This ratio, approximately 15 times revenue growth per additional employee, demonstrates the leverage of AI-native business models and Perplexity’s role as an aggregator that directs queries across various AI providers rather than developing its own advanced models.
“Every time any of the AI improves, our unified system also enhances because we route across all of them,” Srinivas stated. The growth rates of AI-native companies that are attracting investment away from traditional SaaS firms are partly made possible by this kind of structural efficiency, where the product advances alongside its underlying providers without corresponding cost increases.
The hybrid compute platform applies this reasoning to hardware. If Perplexity can utilize the computing resources already available on users’ desks to manage a significant portion of inference tasks, it will lower the marginal cost per query and enhance response times for simpler tasks. As AI increasingly integrates into enterprise processes, determining who bears the cost of compute—whether it's the cloud provider, the AI firm, or the user’s own hardware—will become a critical factor in competition.
Other articles
 Microsoft reveals Project Solara: an operating system designed for agent-first devices.
Microsoft's Project Solara is an innovative platform for devices that operate using AI agents in place of traditional apps. Two concept designs, one resembling a badge and the other a desk device, are currently being tested with Best Buy, CVS, Levi's, and Target.
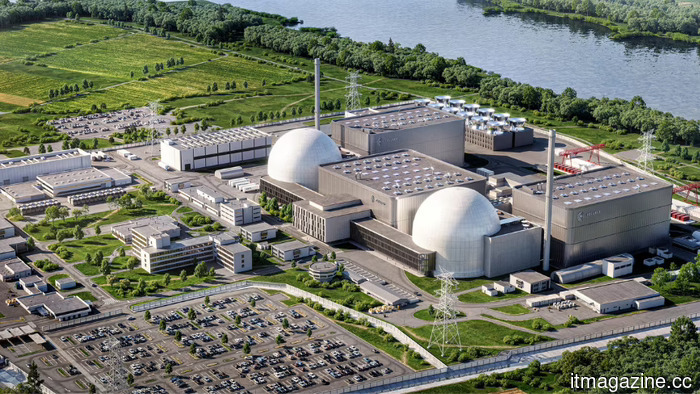 Focused Energy secures $240 million to commercialize NIF laser fusion technology.
German fusion startup Focused Energy has secured $240 million in Series A funding, led by utility company RWE, to develop a laser-powered reactor inspired by the net energy gain breakthrough achieved by the NIF.
 The Asus Pad appears to be a bold imitation of the iPad, yet it seems to offer a sturdy OLED Android tablet experience.
Computex 2026 This article is part of our reporting on Computex, the largest computing conference in the world. Updated less than 5 hours ago ASUS has officially introduced the new Asus Pad, and it's clear where the inspiration comes from. With its flat metal body, uniform bezels, and features like magnetic keyboard attachments and stylus compatibility, the […]
 OpenAI Codex is extending its reach to enterprises through Sites, plugins, and support for non-developer users.
OpenAI has transformed Codex into an enterprise platform, featuring hosted web applications, 62 business application plugins, and 110 skills. Among the 5 million weekly users, non-developers make up 20% and are growing three times faster.
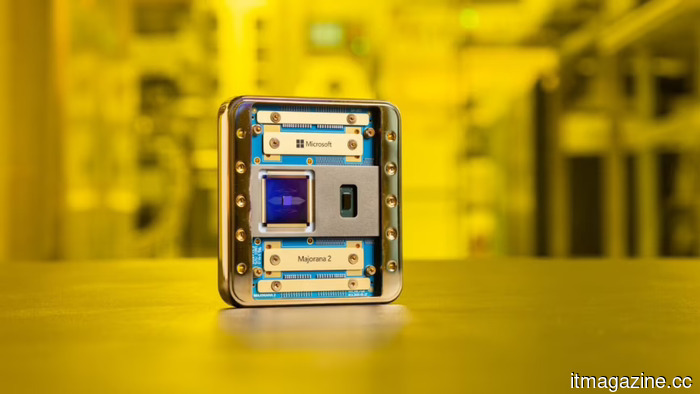 Microsoft's Majorana 2 quantum chip boasts reliability that is 1,000 times greater, with a goal set for 2029.
Microsoft's Majorana 2 qubits can last 20 seconds, compared to microseconds for competitors, and are developed using agentic AI. The company is now aiming to create a scalable quantum computer by 2029.
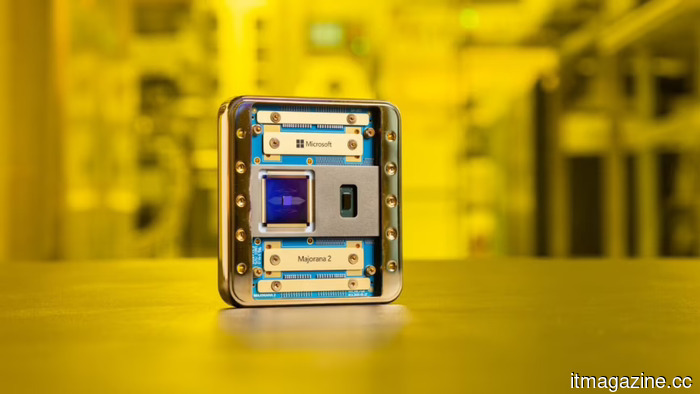 Microsoft's Majorana 2 quantum chip boasts a reliability improvement of 1,000 times and aims for a 2029 launch.
Microsoft's Majorana 2 qubits have a duration of 20 seconds, compared to microseconds for competitors, and are developed using agentic AI. The company aims to achieve a scalable quantum computer by 2029.
Perplexity divides AI inference between personal computers and the cloud to reduce expenses.
Perplexity AI has developed a real-time routing system that distributes AI tasks between personal computers and cloud servers, which was disclosed at Computex in conjunction with Intel, as revenue reaches $500 million.